Agree
Take approved, anonymized traces from three teams. Build a small jointly approved test set.
Evaluation example / methodology, not customer proof
Eight seeded fixture runs show a controlled example of task variation. They do not establish production reliability or customer impact.
Exactly-one-draft criterion
No sampled confidence interval is claimed for these deliberately constructed fixtures.
Candidate v0.9 / fixed synthetic seeds / timeout
Duration ≠ task success
The dot plot reports illustrative duration while color and text identify duplicate artifacts. The task criterion remains independent.
| Seed | Seconds | Drafts / timeout |
|---|---|---|
| 101 | 82 | 1 |
| 102 | 91 | 1 |
| 103 | 87 | 1 |
| 104 | 118 | 2 |
| 105 | 96 | 1 |
| 106 | 103 | 1 |
| 107 | 89 | 1 |
| 108 | 132 | 2 |
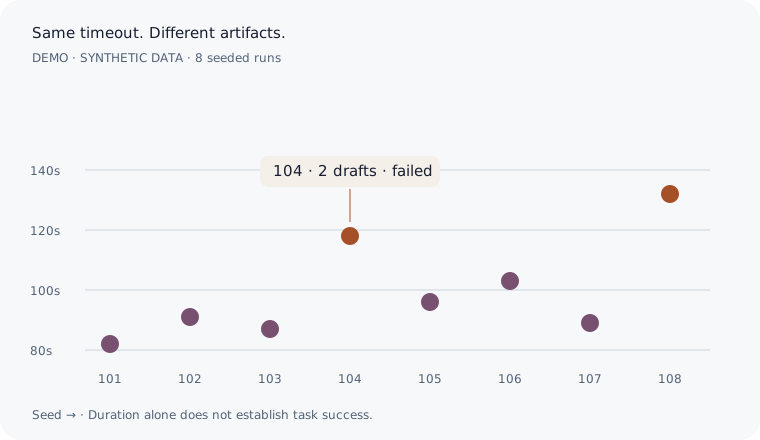
8 synthetic durations, 82–132 seconds; seeds 104 and 108 create duplicates
Proposed buyer experiment
Take approved, anonymized traces from three teams. Build a small jointly approved test set.
Blind-compare the readout against each team’s existing LangSmith, Braintrust, or internal gate.
Advance with an independently confirmed missed regression and an engineering lead’s funded trial or real gate commitment.
A smaller test. A clearer decision.
Agree on one task criterion, an approved fixture, and a named engineering owner.
Request a replay study